technical debt

Ancestor tags:

Caoimhe

ꙮ 彁

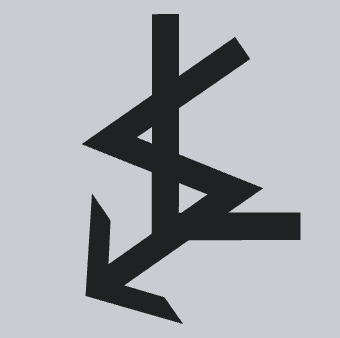
The title of this post is three unusual Unicode codepoints, each having an interesting history as written characters.1 There are many oddities tucked away in the Unicode standard. A recent toot reminded me of ⍼, known as “angzarr”, a symbol that became part of Unicode due to its inclusion in a historical typographic catalogue despite no other prior usage of the glyph having been documented.

abadidea @0xabad1dea@infosec.exchange

My discord has an emoji named "tech debt" - which is just the angzarr, ⍼, the symbol famous for having no known use or agreed-upon meaning but somehow appearing in unicode and now it's just a part of unicode forever.

With so many enormous tech debt bills coming due recently, perhaps you, too, would like to take a moment to appreciate the tasteful angles of the angzarr.

the unicode 'angzarr' symbol, which is a jagged lightning-bolt-like arrow superimposed over a right angle

Technical debt is the labour cost of maintaining a system and all previous choices made when establishing that system. By including this symbol Unicode has created meaning for it and generated usage that would be broken if the symbol was ever removed from the standard or replaced with a different glyph, a problem which the glyph itself is, in one Discord server at least, being used to embody.

There are other interesting cases. The first character in the title of this post is ꙮ, “multiocular O”, a glyph that, before its inclusion in Unicode, was only found as a visual flourish in a single 15th century manuscript in the phrase «серафими многоꙮчитїи», “many-eyed seraphim”. Particularly on Tumblr this has taken off an aesthetic marker of “biblically accurate” or eldritch creatures, those beings beyond human comprehension, or as part of a way of writing speech that is impossible for normal humans to speak, hear, or understand.

The last character in the title, 彁, is a ghost character; characters originally in a Japanese Industrial Standards character set despite having no known usages that then made their way into Unicode as well.2 Ghost characters have also seen use that leans into their strange, alien, nature as words that are included in the Japanese language in some official capacity while carrying no meaning. The Taiko no Tatsujin rythm game series features an extremely difficult song called 「彁」(“ka”) themed after corrupted data (flashing lights warning for this music video). People love to derive meaning from from symbols, even when that meaning is their inherent meaninglessness.

The middle character in the title is actually an Ogham space character, the only whitespace encoded in Unicode that is not blank, a standard of written Ogham that is representative of how it originally existed not as script on a page or even the flat side of a tablet, but as a writing system defined by 3D space, carved onto the edge of monument stones, now leaving a trace in the Unicode standard as a unique space marker. This isn’t really the same as the other examples in this post but I like Ogham and wanted to shoe-horn it in.

  1. Apologies if the characters used in this post don’t render on your computer. ↩

  2. The JIS symbol, 〄, is itself included in Unicode. ↩


Caoimhe

What I’m reading vol. ⅩⅤ

Vols.: Ⅰ, Ⅱ, Ⅲ, Ⅳ, Ⅴ, Ⅵ, Ⅶ, Ⅷ, Ⅸ, Ⅹ, Ⅺ, Ⅻ, ⅩⅢ, ⅩⅣ, ⅩⅤ, ⅩⅤⅠ

I find myself feeling rather inarticulate this afternoon as I sit down to write this, so my comments on each piece shall be brief.


Games

Sandustry is the first factory simulation game I've played that gets heaps right — Edwin Evans-Thirlwell

Sandustry is probably the first factory game I've played that really communicates the physicality of industrial waste, the appalling magnificence of it, for all the dinkiness of its 2D artstyle. It's the only factory game that really makes me think of post-industrial landscapes, like those colossal spoil piles above Aberllefenni. It also engineers a weird exuberance inside the concept of 'byproduct'.

It’s been added to my Steam wishlist.


Technology

CD-ROM Journal - A Trip to 90s Kansai: Exploring the XD FirstClass Network BBS — Misty De Méo

I gestured briefly at the PASSTHRU folder earlier, but I really want to dig deeper into that because this is something very cool. I said before that when you're connecting to a BBS like this, you're connecting to one system rather than the internet as a whole. This is a bit of an exception to that. FirstClass had support for what they called "relays", which allowed BBSs running the same software to talk to each other and exchange messages. It wasn't a realtime connection; this still isn't the internet. It's a little bit more like snail mail. The servers would sync with each other every day, or once every few days, fetching new replies in the conferences they were sharing and transmitting any replies that had been made from a different server. It's quite a bit more "slow internet" than we'd probably tolerate today, but in the pre-internet era the idea you could be talking to these other communities at all would have felt revolutionary.

A really interesting look at early digital communication.


La Fin: I've finished remaking all the websites in H2O: Just Add Water — Alyx Wijers

A little over a year ago, I published a post (“I wasted $410 recreating a fake website that shows up for 10 seconds of a TV show almost no one remembers “) about having re-created a website that showed up for a few seconds in an episode “H2O: Just Add Water”. In the title I described it as “…a TV show almost no one remembers”, which was evidently incorrect, because after posting on Mastodon I discovered that it seemed to be widely known amongst German audiences.

There’s one more fake website that appears in H2O: Just Add Water: greekmythicalcreatures.com

This is just very cute.


An interactive introduction to the terrific experience of rendering Arabic typography and its technical debt — Saleh

To understand why every machine since Gutenberg has wrestled this script and mostly lost, you need one structural fact: Arabic is cursive always. There is no print-versus-handwriting distinction, no block letters. The letters connect in stone inscriptions, in manuscripts, in metal, on screens. Each letter therefore changes shape depending on its neighbours (an isolated form, an initial, a medial, a final), and six letters refuse to connect forward at all, which breaks words into joined clusters and gives the script its rhythm. The shapes are not costumes over some underlying "real" letter. The positional variation is the letter.

Really good read on the history of digital typography for Arabic. Seen from Natalie Weizenbaum sharing it. Speaking of…


I really do think you should learn to use the Linux command line. — Bruno Dias & Natalie Weizenbaum

I really do think you should learn to use the Linux (or Mac, I suppose) command line if you can find the time at all. It is, genuinely, a dramatically more empowering way to use your computer than the alternative, and it will enable to think about your computer as a tool in ways that are completely different.

Cocosigning this post and Weizenbaum also gives a nice quick primer of navigating the command line.


Why do projects reject AI contributions? — Darío Samo

If we were to go by actual lines of code, generated projects easily contain over tens to hundreds of times more documentation and code than human-made ones do. This is intentional by design: the AI companies do not want these projects to be maintainable by anything but their tooling, so you'll have no choice but to keep paying them to work on it.

A good Reddit post from an accomplished game modder on the problems of maintaining or working with generated codebases.


Politics

The End of Trans Rights in the UK Is the Start of Democratic Collapse — Toby Buckle

Unlike, say, Brexit which had rights implications but could point to democratic inputs (however flawed), nothing in the story I told above was backed by any democratic input of any kind. In fact, all of it was elites acting in explicit defiance of the democratic inputs they did receive.

Buckle hammers home how utterly undemocratic the movement against trans rights in the UK is.


The Real Class Politics Behind Ireland’s Fuel Protests — Conor McCabe

The oft-used phrase, squeezed middle, may indeed apply here – not in the mainstream media meaning of cost-of-living and prices, but rather in terms of position-of-production and power. There is of course a qualitative difference between a pushbike and heavy goods vehicle, but when seen in terms of mode and relations of production that difference somewhat fades.

A Marxist analysis of the class position of the Irish fuel protests from earlier in the year.


The End of the 100 Year Government — Simon McGarr

Protection of the property-owning class has been the water that Irish politics swims through, invisible to its fishy participants but explaining nearly everything. It is why our housing crisis exists and why it cannot, apparently, be solved. Solving it would mean a political evolution on a scale of growing legs and lungs and actually climbing out of that water.

An essay on the class priorities of the Irish governments of the last century.


History

The Workers and the Tombs of the Ancient Dead — Margaret Killjoy

Last week I researched the first labor strike in known history. The tomb builders living in a town called Deir el-Medina in Egypt went on strike on November 14th, 1152 BCE. Three thousand, one hundred, and seventy-eight years ago. And their strike looked an awful lot like ours today. They set down their tools and staged sit-ins, they blocked roads, they marched, they engaged in workplace sabotage. They wrote letters to the authorities requesting a redress of grievances. They stole from work. They did everything that we do today.

And a meditation on labour struggle throughout history.


The Empresa de China & the Hapsburg Bid for World Supremacy — Nathan Goldwag

The Jesuits proposed an invasion force to be spearheaded by 10,000 Spanish and Portuguese troops, augmented by 6,000 Filipino auxiliaries and between 5,000-7,000 Japanese Christian mercenaries, leading a two-pronged invasion through Guangdong and Fujian.

A part of colonial history that I had no idea of.

Caoimhe

Migrating comments from Cusdis to Comentario

The story so far: I was using Cusdis to provide a comments section for the bog but it proved to be broken and unmaintained so I replaced it with a self-hosted instance of Comentario.

I am going to walk through what I did to set up Comentario and import old comments from Cusdis. This is not a guide and the scripts that are posted below have serious problems that should be fixed before being used and I am not going to be the one to do that and you would obviously need to change any references to oakreef.ie to your own site.

Subdomain

First of all I needed to have an address to host the Comentario instance at. I chose a new subdomain at comments.oakreef.ie and had to update my Let’s Encrypt certificates to cover that new subdomain. I did not save the commands I used to do that but it was pretty straightforward to do from the command line.

Docker

Then I installed Docker on my server and following Damien’s example with a few tweaks I created my docker-compose.yml and secrets.yaml files.

docker-compose.yml

version: '3'

services:
  db:
    image: postgres:17-alpine
    environment:
      POSTGRES_DB: comentario
      POSTGRES_USER: {INSERT POSTGRES USERNAME HERE}
      POSTGRES_PASSWORD: {INSERT POSTGRES PASSWORD HERE}
    ports:
      - "127.0.0.1:5432:5432"

  app:
    restart: unless-stopped
    image: registry.gitlab.com/comentario/comentario
    environment:
      BASE_URL: https://comments.oakreef.ie/
      SECRETS_FILE: "/secrets.yaml"
    ports:
      - "5050:80"
    volumes:
      - ./secrets.yaml:/secrets.yaml:ro

secrets.yaml

postgres:
  host:     db
  port:     5432
  database: comentario
  username: {INSERT POSTGRES USERNAME HERE}
  password: {INSERT POSTGRES PASSWORD HERE}

Changing the ports configuration to 127.0.0.1:5432:5432 means that the Postgres database is only accessible from the server locally and not publicly available. I also don’t have an email setup for the Comentario instance currently.

Launching the instance is then just a matter of:

sudo docker compose -f docker-compose.yml up -d

Nginx

Then I needed to modify my Nginx config to direct comments.oakreef.ie to the Comentario instance running on port 5050.

server {
	server_name comments.oakreef.ie;

	listen 443 ssl;

	ssl_certificate     /etc/letsencrypt/live/oakreef.ie/fullchain.pem;
	ssl_certificate_key /etc/letsencrypt/live/oakreef.ie/privkey.pem;
	include /etc/letsencrypt/options-ssl-nginx.conf;
	ssl_dhparam /etc/letsencrypt/ssl-dhparams.pem;

	location / {
		proxy_pass http://127.0.0.1:5050;
		proxy_redirect off;
		proxy_http_version 1.1;
		proxy_cache_bypass $http_upgrade;
		proxy_set_header Upgrade $http_upgrade;
		proxy_set_header Connection keep-alive;
		proxy_set_header Host $host;
		proxy_set_header X-Real-IP $remote_addr;
		proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
		proxy_set_header X-Forwarded-Proto $scheme;
		proxy_set_header X-Forwarded-Host $server_name;
		proxy_buffer_size 128k;
		proxy_buffers 4 256k;
		proxy_busy_buffers_size 256k;
		add_header Cache-Control "private";
	}
}

Importing comments

Once there were a few comments on the new system I used the export feature in Comentario to get a JSON file and looked at how Comentario defined comment data in that. I also manually went through all the comments on the old system and made a basic CSV file of all of them with the author name, date posted, the URL of the post the comment was on and the text of each comment. I then wrote this Python file to take the exported Comentario comments—named basedata.json—and the CSV with the old Cusdis comments—comments.csv—and exported a new file with the combined data in the Comentario format.

There are some problems with this!

  1. When importing data Comentario does not check for duplicates. I ended up creating duplicates of all the new Comentario comments that already existed on the site doing this and had to manually delete them. If you are doing this do not include existing comments as part of the file you are creating to import.
  2. I did not include replies at all. I decided to try importing replies I had made to people as a second, separate, step (see the second Python script below). This made things more awkward down the line. Do everything in one batch.
import csv
import json
from datetime import datetime, timezone
from dateutil.parser import parse
from pprint import pprint
from uuid import uuid4

now = datetime.now()
pages = {}
site_url = 'https://oakreef.ie'
date_format = "%Y-%m-%dT%H:%M:%SZ"

my_id = "ADMIN USER UUID"

with open('comments.csv', newline='') as csv_file:
		csv_reader = csv.reader(csv_file, delimiter=',', quotechar='"')
		for row in csv_reader:
				author, date, url, text = row
				date = parse(date)
				
				if url not in pages:
					pages[url] = {
						'comments': []
					}
				
				pages[url]['comments'].append({
					'author': author,
					'date': date,
					'text': text
				})


with open('basedata.json') as json_file:
		data = json.load(json_file)

domainId = data['pages'][0]['domainId']

for url, page in pages.items():
	page_id = str(uuid4())
	data['pages'].append({
		'createdTime': now.strftime(date_format),
		'domainId': domainId,
		'id': page_id,
		'isReadonly': False,
		'path': url,
	})

	for comment in page['comments']:
		comment_id = str(uuid4())
		data['comments'].append({
			"authorCountry": "IE",
			'authorName': comment['author'],
			'createdTime': comment['date'].strftime(date_format),
			"deletedTime": "0001-01-01T00:00:00.000Z",
      "editedTime": "0001-01-01T00:00:00.000Z",
      "html": f"\u003cp\u003e{comment['text']}\u003c/p\u003e\n",
			'id': comment_id,
			'isApproved': True,
			'isDeleted': False,
			'isPending': False,
			'isSticky': False,
			'markdown': comment['text'],
			"moderatedTime": comment['date'].strftime(date_format),
			'pageId': page_id,
			'score': 0,
			'url': f'{site_url}{url}#comentario-{comment_id}',
			'userCreated': '00000000-0000-0000-0000-000000000000',
			"userModerated": my_id
		})


with open('import.json', 'w') as import_file:
	json.dump(data, import_file)

When that was done I put it away for a while as I wasn’t feeling well and eventually came back to do replies. I, again, manually went through all replies I had made to comments on the old system and made a CSV file with the reply date, URL of the page, the UUID of the parent comment as it existed in the new Comentario system, the UUID of the page the parent comment is on in teh new Comentario system and the text of the reply.

Two things are important to note about this:

  1. It was a pain in the hole. If I had done replies at the same time as the rest of the comments I could have used the UUIDs that I was generating in the script rather than going to find them manually and making them into a CSV.
  2. The initial upload failed as apparently Comentario couldn’t match the page and user IDs to what was in the database and it needed those to be in the import file. I got around this by doing another export and copying the entries for pages and commenters from that into the new one and uploading. This was not a good way to do this! It could have gone badly or had unexpected side effects. Again, if you’re doing this do not import comments and replies as two separate steps!
  3. It still didn’t fully work anyway. My replies did import and do show up on the right pages but they are not nested properly as replies. It’s like looking at a comment section on a very old Youtube video where reply chains are broken and everything just displays as individual comments. I don’t think that I am going to bother trying to fix this as I don’t have that many comments on this site and I think everything reads understandably as it is but if you want to try this approach you will want to figure out a way of not fucking up importing the replies.
import csv
import json
from datetime import datetime, timezone
from dateutil.parser import parse
from pprint import pprint
from uuid import uuid4


now = datetime.now()
site_url = 'https://oakreef.ie'
date_format = "%Y-%m-%dT%H:%M:%SZ"

my_id = "ADMIN USER UUID"

data = {
  "version": 3,
  "comments": [],
}

with open('replies.csv', newline='') as csv_file:
		csv_reader = csv.reader(csv_file, delimiter=',', quotechar='"')
		for row in csv_reader:
				date, url, parent_id, page_id, text = row
				date = parse(date)

				comment_id = str(uuid4())

				data['comments'].append({
					"authorCountry": "IE",
					"createdTime": date.strftime(date_format),
					"deletedTime": "0001-01-01T00:00:00.000Z",
					"editedTime": "0001-01-01T00:00:00.000Z",
					"html": f"\u003cp\u003e{text}\u003c/p\u003e\n",
					"id": comment_id,
					"isApproved": True,
					"isDeleted": False,
					"isPending": False,
					"isSticky": False,
					"markdown": text,
					"moderatedTime": date.strftime(date_format),
					"pageId": page_id,
					"parentId": parent_id,
					"score": 0,
					"url": f'{site_url}{url}#comentario-{comment_id}',
					"userCreated": my_id,
					"userModerated": my_id
				})


with open('reply-import.json', 'w') as import_file:
	json.dump(data, import_file)

My avatar

One last thing is that Comentario doesn’t allow GIF avatars, but I like my sparkly Jupiter. After looking at the Postgres database I could see that user avatars are simply stored as binary data in the table cm_user_avatars with three sizes avatar_l, avatar_m and avatar_s corresponding to 128×128, 32×32 and 16×16 pixels, respectively, so I made some GIFs in the appropriate sizes, converted them to binary strings, and overrode the avatar_l and avatar_m entries in the cm_user_avatars table manually (I left the avatar_s as a JPEG).

UPDATE cm_user_avatars SET avatar_m = '\xBINARY_DATA_HERE'  WHERE user_id = 'UUID_HERE';

This seems to work without any problems and my avatar in my own comments section is sparkly now.

Conclusions

That’s it I hope I don’t have to worry too much about this setup again for some time.


concept: rewrite a bunch of my website code to split out sections from each other more cleanly so I can more easily make small posts with less effort

result: oh god oh fuck everything is broken and I have way to many unstaged changes what was I in the middle of doing a week ago before I went on holiday if I want to post anything I need to stash fifty files and change branches which takes several minutes right now

Though honestly that describes the situation more a week ago than right now. I do have the podcast processing stuff finished now and I just need to do similar rewrites with the Pico-8 processing. That should🤞🏻 be easier now that I have done the podcast stuff and can base what I do on how I handled that.